Insights

Student Data in AI Model Training: A District Guide

Learn how K-12 districts enforce strict contractual bans on AI model training, close telemetry loopholes, and protect student privacy.

Published By SchoolAmplified Editorial Team 9 min read
  • Superintendents
  • Chief Technology Officers
  • Assistant Superintendents of Curriculum
  • District Legal Counsel
  • School Board Members
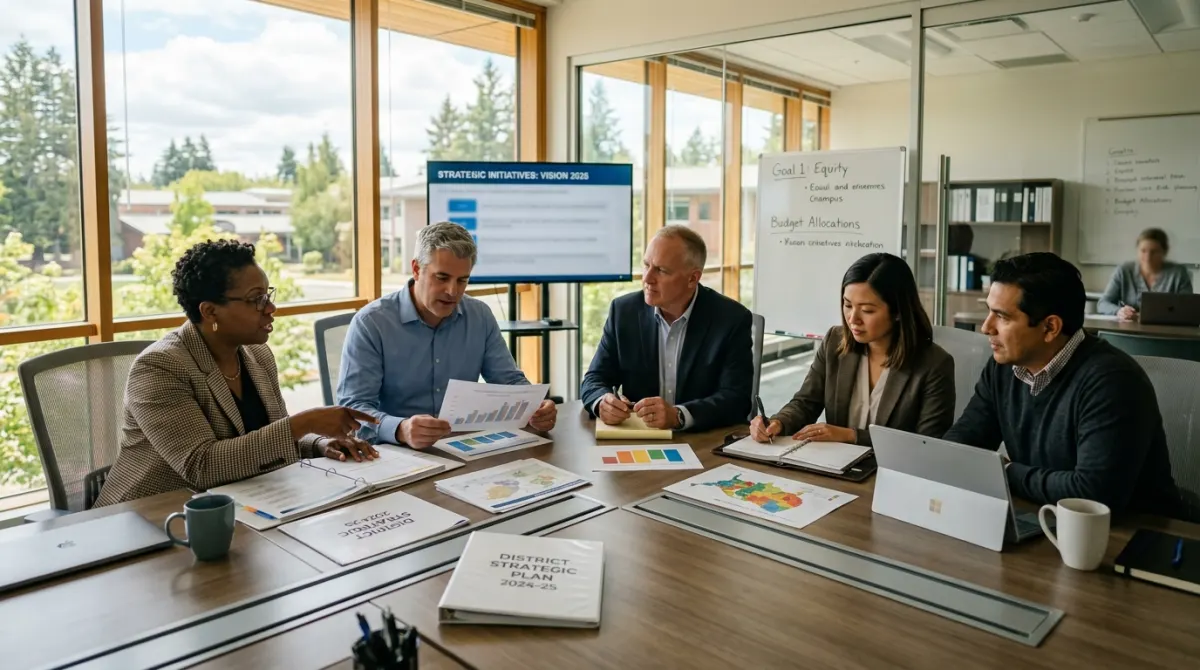
District leadership team reviewing vendor data privacy agreements and AI model training contract clauses around a conference table.

9 min read

Governing AI Data in K-12 Contracts

Contractual guardrails, zero-training verification, and telemetry controls for school districts.

When school districts procure digital instructional tools or operational software, district leaders traditionally rely on standard Student Data Privacy Agreements (NDPAs) and Family Educational Rights and Privacy Act (FERPA) compliance language. However, the rapid proliferation of generative artificial intelligence across educational software has rendered legacy procurement templates inadequate. In generative AI environments, student interactions generate rich text prompts, voice inputs, behavioral keystrokes, and creative outputs that vendors can ingest into foundation models or use for proprietary algorithm refinement unless explicitly prohibited by binding contract clauses.

Local education agencies (LEAs) face heightened scrutiny from families, school boards, and state education agencies regarding how commercial AI vendors handle student intellectual property and personally identifiable information (PII). In policy guidance released in September 2026, the osse.dc.gov emphasized that LEA procurement policies must ensure vendors are strictly prohibited from leveraging student data for model training, product improvement, or any commercial purposes outside the contracted service. To safeguard student privacy, districts must move beyond boilerplate terms and implement enforceable, technical contractual boundaries.

The Expanding Scope of Student Data in Generative AI

Traditional educational software primarily collected structured data records: student rosters, attendance logs, standardized test scores, and demographic identifiers. Generative AI tools capture an entirely new tier of sensitive data. When students engage with AI writing assistants, automated tutors, or conversational research agents, they generate unstructured data streams containing personal reflections, voice recordings, behavioral nuance, and academic struggles.

National standards and negotiated frameworks have expanded the definition of protected student data in AI environments. As reported by edweek.org, historic binding agreements established through the National Academy for AI Instruction apply an intentionally broad definition of student data. This definition encompasses not only directory information and academic grades, but also user writing prompts, conversational memory files, work outputs, keystroke cadence, and eye-tracking telemetry that could reasonably be linked to individual students.

When districts enter vendor relationships without updated AI-specific data riders, they risk exposing this broad spectrum of student intellectual property to commercial model training datasets. Once user data is absorbed into a large language model's neural network weights during training or reinforcement learning from human feedback (RLHF), that data cannot simply be excised through a standard database deletion request. Establishing proactive boundaries is the only reliable method for preventing student data ingestion.

Why Standard FERPA Agreements Fail to Block AI Training

Many legacy vendor agreements permit service providers to utilize 'de-identified,' 'anonymized,' or 'aggregated' customer data for product enhancement and research. In traditional database architectures, aggregating anonymized metrics presented minimal privacy exposure. In generative AI ecosystems, these de-identification exemptions represent significant data privacy loopholes.

Research compiled by the ecs.org reveals that standard software procurement policies across states often lack provisions addressing AI-specific concerns. These include model pretraining verification, human-in-the-loop safeguards, bias auditing, and explicit bans on training algorithms with student data. When a vendor claims that user prompts are 'anonymized' before being fed into a training pipeline, the model can still capture semantic patterns, linguistic traits, or unscrubbed PII embedded within open-text essays. District leaders must review their vendor contracts in alignment with governing AI data boundaries to eliminate standard de-identification clauses that allow commercial model fine-tuning.

Furthermore, generative AI systems frequently process inputs through third-party foundation model APIs. Even if a direct software vendor pledges compliance, its underlying infrastructure partners may log or retain user prompts for system maintenance or model calibration. Districts must ensure that privacy commitments extend down through all cloud hosting environments and foundation model sub-processors as detailed in our AI telemetry and subprocessors guide.

Essential Contract Language to Prohibit Model Training

To establish ironclad protections, district legal counsel and technology directors must incorporate mandatory AI addenda into every instructional and operational technology contract. These addenda must replace generic privacy statements with precise, non-negotiable legal restrictions.

Every procurement contract involving artificial intelligence should mandate the following core provisions:

  1. Zero Model Training Clause: The vendor explicitly warrants that no customer data—including student inputs, educator prompts, uploaded documents, audio recordings, or generated outputs—shall be used to train, retrain, fine-tune, or validate any public or proprietary machine learning models, foundational models, or algorithmic components.
  2. Immediate Data Ephemerality: User prompt inputs and generated outputs must be processed purely via stateless API calls or isolated inference sessions. Data persistence must be restricted to the minimum operational duration required to deliver the immediate user session, with zero retention in secondary vendor logs beyond 30 days for transient security debugging.
  3. Binding Sub-Processor Adherence: All contractual restrictions prohibiting model training, data aggregation, and secondary commercial use must bind every subcontractor, infrastructure provider, and third-party foundation model partner utilized by the primary vendor.
  4. Pretrained Architecture Attestation: Consistent with model state frameworks noted by the ecs.org, vendors must provide written verification that candidate systems are fully pretrained and that human-in-the-loop review protocols were deployed responsibly during initial system development without exploiting unauthorized K-12 datasets.
District Perspective

The work gets easier when teams operate from shared information

Communication, continuity, and implementation improve when the model is more coordinated.

  • Require explicit contractual guarantees prohibiting vendors from using student inputs, work outputs, and telemetry for model training or commercial fine-tuning.
  • Establish strict audit protocols verifying zero data retention, closed inference boundaries, and WCAG 2.1 AA accessibility compliance across all AI tools.
SuperintendentsChief Technology OfficersAssistant Superintendents of Curriculum
The work gets easier when teams operate from shared information

District context

The work gets easier when teams operate from shared information

Communication, continuity, and implementation improve when the model is more coordinated.

Districts should require vendor executive leadership to sign these attestations before moving software into classroom micro-pilots or full enterprise deployments.

Distinguishing Legitimate Telemetry from Behavioral Profiling

Vendors routinely gather diagnostic telemetry to monitor application uptime, detect latency bottlenecks, and fix software bugs. However, in AI-infused platforms, the boundary between technical error logging and commercial user profiling can blur rapidly. K-12 contracts must clearly delineate permitted technical logging from unlawful behavioral tracking.

Permitted telemetry should be limited strictly to non-content system metrics, such as server response times, API error codes, token usage volumes, and browser compatibility flags. In contrast, vendors must be legally barred from collecting or analyzing:

* Behavioral Profiling: Analyzing keystroke speed, mouse trajectories, or hesitation patterns to construct psychometric or behavioral profiles of students.
* Commercial Inferences: Drawing inferences regarding student emotional states, political views, socioeconomic background, or cognitive capacity for marketing or advertising purposes.
* Secondary Monetization: Aggregating student interaction metadata to sell market trend reports or optimize third-party software products.

As reinforced in binding agreements cited by edweek.org, telemetry data permitted for debugging and platform reliability must remain strictly de-identified and prohibited from feeding AI training datasets or behavioral targeting systems. Districts must mandate that all telemetry configurations default to the most restrictive privacy settings.

Universal Accessibility and Algorithmic Equity Standards

Data protection and model safety cannot be evaluated in isolation from instructional equity. When an AI system operates within a classroom, its underlying algorithms directly influence student learning trajectories. If an algorithm generates inaccurate, biased, or inaccessible instructional content, it violates district obligations under federal civil rights laws and the Individuals with Disabilities Education Act (IDEA).

Guidance from osse.dc.gov highlights that LEA policies must require vendors to demonstrate documented steps taken to mitigate algorithmic bias and verify compliance with recognized cybersecurity and privacy frameworks. In parallel, instructional AI tools must deliver rigorous accessibility. As outlined in our guide on vetting AI-infused curriculum, all dynamic AI-generated text, diagrams, and conversational interfaces must strictly comply with Web Content Accessibility Guidelines (WCAG) 2.1 Level AA standards.

District evaluation committees must verify that AI software supports dynamic screen-reader compatibility via live ARIA regions, generates automated descriptive alternative text for real-time diagrams, and offers full keyboard operability for assistive technology users. AI tools designed to simplify text must allow classroom educators to calibrate reading levels without stripping out essential grade-level academic vocabulary required by state standards.

Verification Checklists and Technical Audit Requirements

Contractual promises are only as dependable as a district's ability to verify them. Technology departments must establish formal technical audit protocols to ensure vendors adhere to their data boundary commitments throughout the software lifecycle. Relying solely on vendor marketing claims creates unacceptable compliance exposure.

Before authorizing software deployment, district technology teams should execute the following verification checklist:

| Verification Dimension | Verification Method | Mandatory Compliance Standard |
| :--- | :--- | :--- |
| Data Isolation | Infrastructure Review | Isolated tenant databases; dedicated enterprise API endpoints with zero-retention logging. |
| Model Fine-Tuning | Vendor Legal Attestation | Legally binding zero-training agreement signed by vendor CISO or General Counsel. |
| Access Controls | Security Assessment | SAML 2.0 / SSO integration, multi-factor authentication (MFA) for administrative roles, role-based access controls. |
| Encryption Protocols | Cryptographic Audit | AES-256 encryption at rest; TLS 1.3 encryption in transit across all internal and external network hops. |
| Sub-Processor Transparency | Third-Party Registry | Complete list of all cloud hosting vendors and foundational model APIs with verified privacy addenda. |
| Accessibility Compliance | Technical Testing | Validated VPAT demonstrating WCAG 2.1 Level AA compliance; screen-reader and keyboard navigation verification. |

District Perspective

District leadership needs clearer signals and stronger communication rhythm

Systems feel more credible when guidance and public experience stay connected.

  • Establish strict audit protocols verifying zero data retention, closed inference boundaries, and WCAG 2.1 AA accessibility compliance across all AI tools.
  • Implement measurable micro-pilot rubrics with mandatory stop conditions to terminate vendor access immediately upon any privacy or safety breach.
District leadership needs clearer signals and stronger communication rhythm

Visible alignment

District leadership needs clearer signals and stronger communication rhythm

Systems feel more credible when guidance and public experience stay connected.

Districts should reserve the contractual right to perform annual third-party compliance reviews or request current SOC 2 Type II audit reports to ensure continued adherence.

Measurable Micro-Pilots and Contractual Stop Conditions

Rather than committing to multi-year district-wide software licenses, academic divisions should run structured, 60-day classroom micro-pilots evaluated against rigorous quantitative benchmarks. These pilots allow educators and IT personnel to observe software behavior in authentic instructional settings before high-stakes implementation.

According to the ies.ed.gov, educational evidence does not support unmanaged technology adoption; it supports thoughtful, guided use bounded by clear guardrails. District micro-pilots must monitor pedagogical impact, student task completion, hallucination rates, and data security adherence.

Crucially, vendor agreements must contain unambiguous contractual stop conditions. A stop condition is a non-negotiable threshold that grants the district the legal and operational authority to immediately suspend software access and terminate the agreement without financial penalty.

Mandatory stop conditions should include:

* Privacy Breach: Any unauthorized transmission, logging, or ingestion of student PII or prompt text into public or shared machine learning datasets.
* Factual Inaccuracy: An empirical hallucination or academic error rate exceeding pre-established pilot thresholds (e.g., > 1% on standard curriculum benchmark queries).
* Safety Failure: Any instance where the AI tool bypasses safety filters to deliver harmful, biased, or age-inappropriate content to a student.
* Accessibility Non-Compliance: Failure to remediate identified assistive technology barriers within 15 calendar days of notice.

To manage these scenarios effectively, district IT leaders should establish clear off-ramps and technical cutoff protocols as outlined in our operating guide on governing district AI off-ramps.

District Knowledge Systems and Governed Communications

Protecting student data from unauthorized AI exploitation does not mean school systems must abandon automation and modern digital workflows. Instead, successful districts separate consumer-grade public AI tools from enterprise-governed knowledge architectures designed specifically for public education.

When school systems centralize their institutional knowledge, policy documentation, and operational communications inside a protected single source of truth, staff can access AI-assisted drafting, multilingual translation, and family messaging without exposing district data to commercial model training. Modern enterprise platforms operate within strict trust framework parameters, executing natural language processing inside secure, zero-retention computational boundaries.

By uniting stringent legal vendor contracts with governed internal communication systems, district superintendents and school boards can confidently protect student intellectual property, ensure regulatory compliance, and maintain community trust across every classroom.